Carbon Peak and Carbon Neutralization Information Support Platform
碳达峰碳中和情报支持平台
Download the Nature Podcast 21 August 2026 In this episode: 00:28 The promise of a new narcolepsy drug Nature: First-of-its-kind narcolepsy drug opens door to new therapies for the brain 05:53 Human brain organoids kept alive for over five years Nature: Human organoids that mimic brain development grown for years in lab Subscribe to Nature Briefing, an unmissable daily round-up of science news, opinion and analysis free in your inbox every weekday. Never miss an episode. Subscribe to the Nature Podcast on Apple Podcasts, Spotify, YouTube Music or your favourite podcast app. An RSS feed for the Nature Podcast is available too.
发布时间:2026-08-21 Nature
The β-galactosidase molecule can be targeted by antibodies in experiments. But some studies have erroneously used the antibody that targets the bacterial β-galactosidase instead of the mammalian version.Credit: Laguna Design/Science Photo Library More than 50 studies on cell ageing have apparently used the wrong antibody to identify a key protein in experiments, according to a science sleuth. The latest case comes two months after Sholto David, a UK-based independent molecular biologist, identified hundreds of studies with a similar error and three months after he and another researcher spotted problems with antibody-validation images in the catalogue of one of the world’s largest suppliers, Thermo Fisher Scientific, headquartered in Waltham, Massachusetts. David reported the latest antibody mix-up in a 21 July post on the research-integrity blog For Better Science. It’s not clear whether the flaws compromise the studies, but David says they might in some cases. Antibodies are a workhorse of biological experiments because they bind to and track specific proteins. But they are also a source of many problems. In some cases, researchers struggle to replicate experiments despite using identical antibodies. In other instances, the antibodies recognize other proteins, as well as the ones they are sold to detect, creating unreliable results. In the latest case, David says that researchers seem to have chosen the wrong antibodies — instead of using ones that target mammalian proteins that are thought to reveal information about ageing, their papers listed antibodies that bind to bacterial proteins. This highlights a larger problem in biology, in which reagents in experiments are used poorly or not adequately characterized, says Aled Edwards, a biochemist at the Structural Genome Consortium in Toronto, Canada. In an ideal world, he says, researchers would validate the antibodies, to check they work as planned, before starting an experiment. But this can be time-consuming and expensive, he adds. He thinks the issue will get worse as more researchers use artificial-intelligence models to review the literature and make predictions about which proteins could be good targets for disease treatments. If the wrong antibodies are reported in papers, it could throw such predictions off, he adds. Cell-ageing studies Researchers studying ageing use an antibody to identify when cells stop dividing but remain alive — a state called senescence. Scientists want to understand this process because non-dividing cells accumulate in tissues, causing inflammation and secreting proteins that can harm nearby cells. A hallmark of senescent cells is the activity of an enzyme called β-galactosidase. By using a mammalian antibody that binds to β-galactosidase, scientists can detect the protein using imaging techniques such as immunostaining or western blotting and, in doing so, theoretically identify senescence. (There is some dispute about whether this technique can accurately flag cells in senescence, but some researchers still use it.) However, David says that he has identified at least 54 papers in which the authors state they used an antibody that targets β-galactosidase from Escherichia coli bacteria. Using this antibody to try to identify β-galactosidase expression in mammalian cells is not going to work, says David. “This is a big blunder,” he writes on the blog. Antibodies that target one mammalian species might react with proteins from another, but “cross-kingdom reactivity is far-fetched, and not supported by the theoretical or experimental evidence”, says David. Some manufacturers that supply E. coli β-galactosidase antibodies state that they might cross-react with other species, but such disclaimers are often generic and most companies will not have experimentally confirmed cross-reactivity, says Jennifer Byrne, a cancer researcher at the University of Sydney in Australia. It’s not clear whether scientists knowingly or accidentally used the E. coli antibody. At least one team that used the bacterial antibody instead of the mammalian one acknowledges in its paper that the results were not as expected. Dan Liebermann, a retired cancer geneticist previously at Temple University in Philadelphia, Pennsylvania, says he mistakenly used the E. coli antibodies instead of mammalian ones in experiments detailed in a 2010 Cancer Research paper1 on cellular stress responses in breast cancer. Liebermann says that the mistake does not affect the work’s conclusions because the E. coli antibody experiments provided only ancillary data. “I did not intend to deceive the scientific community. Everybody overlooked it: my co-authors, collaborators and reviewers,” he says. The editors of Cancer Research did not respond to requests for comment on the issues raised about the paper. Identifying papers David says he first found the issue when when a researcher sent him a paper2 published in Cell that listed an E. coli β-galactosidase antibody used in mouse liver tissue. The corresponding author of the paper, Juan Carlos Izpisua Belmonte at Altos Labs in San Diego, California, declined to comment on the matter. Cell says that it is looking into it. After seeing the Cell paper, David says, he found three other manufacturers of β-galactosidase antibodies that target E. coli, which researchers have seemingly used for the wrong application in another 53 papers. The papers were published in a range of journals, from high-profile ones (including Cell and Nature Aging), to less influential titles. (Nature’s news team is independent of the journals teams.) Tim Kersjes, head of research integrity, resolutions, at Springer Nature, says the team will assess the concerns raised in the blog. “If our assessment confirms the validity of these respective concerns, then we will take appropriate editorial action,” he says. Bigger case The latest mix-up is smaller in scale and significance, David says, than the incident reported on the same blog in June. Here, cancer and ageing researchers mistakenly used antibodies that bind to the p16-ARC protein, which is important in shaping a cell’s molecular skeleton, instead of antibodies that bind to the p16INK4a protein, which suppresses tumour growth. In some of those cases, David says, researchers used the correct antibodies in their experiments but reported the wrong name in the resulting paper. The way that antibodies are named, often with a string of letters and numbers, makes it easy for researchers to mix them up, says Byrne. The issue of confusing p16-ARC and p16INK4a antibodies has affected more than 300 papers. So far, at least one journal has issued a correction, and another publication noted on the post-publication peer-review site PubPeer that it was investigating another paper. Several authors of other papers named by David in a spreadsheet linked to the June blog say on PubPeer that they plan to correct their published work. Others say that the mistakes do not affect the central conclusions of the work or that they plan to redo the experiments with the correct antibody. David says he is not done with investigating antibody mix-ups. He says he is now working on another case, which is likely to be the biggest one yet.
发布时间:2026-08-21 Nature
The AI tool was trained on scientific publication-patent pairs.Credit: IB Photography/Alamy Investors and technology-transfer offices expend enormous effort trying to spot commercially promising research before it reaches the point of patenting. Now, a machine-learning tool is aiming to speed up this process by scoring how ‘patent-like’ a scientific paper is — months or years before any deal, patent filing or spin-off company reveals its commercial potential. And it’s one of many proffering the same capability. The tool, called the Translation Readiness Index (TRI), performs a linguistic analysis of a paper’s title and abstract. It then measures how similar a paper’s vocabulary is to publications that have previously been paired with patents. The method was developed by researchers at the data-analytics firm League of Scholars in Sydney, Australia. The work was posted as a preprint on arXiv1 and has not yet been peer reviewed. “It’s a new way of triaging or ranking” research, says computational social scientist Paul McCarthy, co-founder of League of Scholars and a co-author on the preprint. The tool estimates the probability that a paper uses “patent-like language”, he says. Picking winners The researchers trained TRI on 20,610 scientific papers, including 9,431 that had been matched to patents. Titles and abstracts were fed into five classifiers, with the best-performing model having a 78% chance of ranking a patent-linked paper above an otherwise comparable paper that was not linked to a patent. Papers that were eventually cited in patents included vocabulary such as ‘prototype’, ‘device’ and ‘design’ more often than did papers that were not cited in patents. TRI analyses only titles and abstracts, so doesn’t directly assess a paper’s underlying data or results. To test whether TRI’s highest-ranked papers were correlated with other markers of commercial activity, such as whether co-authors have industry affiliations and if authors had previously patented research, the researchers looked at the 100 highest TRI-ranked papers by authors at the University of Western Australia (UWA) in Perth. The papers, published between 2019 and 2026, were more likely than a random sample to show those markers: 83 of the 100 papers had industry-affiliated co-authors, and 34 involved at least one UWA-affiliated author who had previously patented research, McCarthy says. As a result, the team is now testing TRI with several universities. Quantum meets capitalism: how to pair long-term bets on technology with commercial speed McCarthy doesn’t recommend basing investment decisions on the tool’s results alone because it’s a probabilistic ranking. However, he says it might help to uncover “unexpected gems”. Ben Miles, co-founder of Empirical Ventures, an early-stage deep-tech investment firm based in London, says the tool could be useful as an external signal for academics and funders wanting to decide which ideas deserve further support from universities, governments or philanthropies before they are mature enough for investors. But patentable technologies aren’t always commercially viable — and so any measurement of that will always be imperfect for investors’ needs. Spin-off scouts TRI is one of several research-scouting tools that aim to identify promising science. Some of the tools are being adopted in research institutes to help identify discoveries that could — with backing — become a viable business. One such tool, called Haystack, was built for the technology team at Cornell University in Ithaca, New York, to scan up to 13,000 papers per year — too many for Cornell’s technology-transfer team to inspect manually, says Matt Marx, who built the tool and is vice-provost for entrepreneurship, innovation and external engagement at the university. How I honed my biopharma dealmaking and business-development skills after my PhD His colleagues are testing a dashboard that ranks Cornell papers by their estimated commercial potential. “I don’t trust this alone,” he says of the ranking. “But I can take this list of 10 or 20 and give it to an expert and say, ‘Is there something here?’” That distinction — between finding candidate technologies and judging them — is important because tools such as Haystack and TRI have their limitations when it comes to predicting commercial successes. For example, it’s unclear whether a paper being cited in a patent is a strong enough proxy for commercial value, says Sharique Hasan, who studies entrepreneurial strategy and innovation at Duke University’s Fuqua School of Business in Durham, North Carolina, and has co-developed a machine-learning system for estimating the commercial potential of scientific discoveries2. Universities patent plenty of inventions that are never licensed and never generate revenue, he says. Hasan says the real value of tools such as TRI is in producing “a smaller set of things to pay attention to deeply”, rather than investors spending their time “constantly searching Google”. And that’s why the approach is so valuable, says Marx. Such AI tools might not be able to pick firm winners yet, but they can help universities to sift through their research systematically and faster than tech-transfer teams can.
发布时间:2026-08-20 Nature
Weeping willow trees are found in many cities globally. Credit: avada/Alamy Across Beijing, millions of weeping willows and poplar trees turn the megacity into a green metropolis. But compounds released by these trees are becoming a major contributor to air pollution1, finds a study. Beijing is not alone. Many trees planted in urban areas — species that are often chosen for their quick growth and climate resilience — are worsening ozone emissions, suggests the study published in Science Advances today. Rising temperatures from global warming could exacerbate the problem. Ozone forms when volatile organic compounds (VOCs) released by some vegetation, vehicles and chemical industries react with nitrogen oxides (NOx), which are emitted mostly by traffic and industry. A series of reactions between these compounds in the presence of sunlight causes ozone to form. Breathing in ozone can inflame or damage the airways, causing breathing difficulties, particularly in people with asthma or lung disease. Co-author Bin Yuan, who studies atmospheric chemistry at Jinan University in Guangzhou, China, says that the team initially set out to understand the impact of human activity on ozone pollution. But they were surprised to find that urban vegetation was a much larger contributor to ozone emissions than previously thought. “When we got this data, we did not believe it in the beginning,” Yuan says. Many tree species emit VOCs, some more than others. Willow (Salix spp.) and poplar (Populus spp.) trees, which have been planted across many cities, release high levels of isoprene, a type of VOC that is produced as a byproduct of photosynthesis. Roughly 35% of the trees in Beijing are isoprene emitters, the team found. Measuring emissions The researchers collected air samples across Beijing to measure VOC concentrations and gathered ozone data at monitoring stations around the city. They found that vegetation accounted for about 10% of the total VOC emissions in Beijing between May and July 2021, the study period, and that human activities, such as vehicle emissions and industrial chemicals, accounted for the rest. Because VOCs don’t directly form ozone, the team needed another way to measure how much vegetation contributed to the city’s ozone pollution. To do that, they estimated how fast VOCs react with hydroxyls in the atmosphere. Hydroxyls react with VOCs to form peroxy radicals, which in turn react with NOx in the air to form compounds that turn into ozone in the presence of sunlight. The study found that vegetation accounted for 52% of the chemicals that go on to form ozone, with isoprene the dominant contributor. Although total VOC emissions from human activities were higher than those from vegetation, their contribution to the formation of ozone was substantially less than that of plants. The researchers also looked at tree species planted in 24 megacities to estimate their potential isoprene emissions. They also found that isoprene emissions in a large proportion of the cities they investigated, including Sydney and Melbourne in Australia, were predicted to be higher than in Beijing. In Sydney, for example, about 65% of the trees emit isoprene. Ian Jamie, an environmental chemist at Macquarie University in Sydney, says that vegetation as a source of VOCs is becoming proportionally larger because other sources have reduced substantially over the past few decades. Emissions from vehicles, which used to be a large source of organic compounds, have reduced, he says. Heat intensifies VOCs and ozone production increase as temperature rises. The study found that at 35 °C, the hydroxyl reactivity rate with VOCs from vegetation was seven times higher than at 20 °C. As a result, the contribution of vegetation to the chemical reactivity rose from 21% at 20 °C to 74% at 35 °C. The researchers also considered Beijing’s urban heat island — the tendency for built-up areas to be warmer than their surroundings. They estimate that a typical heat-island intensity of 0.8 °C during summer daytime, when there is a maximum daily temperature of 32 °C, could increase isoprene emissions from urban trees by 12%. Because of this extra heat, a tree in an urban area is more stressed — and produces more VOCs than would the same tree in a forest, says Robyn Schofield, an aerosol scientist at the University of Melbourne. The researchers say that VOC emissions from urban vegetation could become more pronounced as the globe warms. Yuan cautions that the findings are not an argument against planting trees in cities. Trees provide substantial benefits, including cooling, carbon storage and biodiversity, he adds. But tree selection should become part of urban planning, particularly as climate change increases temperatures and exacerbates heatwaves, he adds. However, Jamie adds that a notable proportion of volatile compounds in the atmosphere still comes from human activities, including petroleum use and solvent industries. He says that focusing on reducing those sources of emissions is important. Another way to reduce ozone formation is by reducing NOx emissions, says Schofield. Without NOx, VOCs cannot contribute to ozone pollution, she adds.
发布时间:2026-08-20 Nature
A cancer vaccine developed by Moderna and Merck reduced the recurrence of melanoma.Credit: Adam Glanzman/Bloomberg/Getty A personalized mRNA vaccine for melanoma reduced the risk of the cancer returning in a phase III clinical trial, the companies behind the trial announced this week. The vaccine — which relies on the same mRNA technology used to develop COVID-19 shots — is the first mRNA-based cancer treatment to show success in a late-stage trial. “It’s incredibly exciting,” says Seth Cheetham, an mRNA scientist at the University of Queensland in Brisbane, Australia. “This is the first really large-scale trial” to release data for a personalized mRNA cancer vaccine. The results put it a step closer to regulatory approval for wider use and could bolster the whole field, he adds. Marco Gerlinger, a medical oncologist at St Bartholomew’s Hospital in London, says the study provides proof of principle that personalized cancer vaccines work. “This is important as they can be designed against many different cancer types,” adds Gerlinger, who is a principal investigator on a trial for a cancer vaccine being developed by BioNTech in Mainz, Germany. The study could have implications beyond the field of cancer, too, says Sam Barrell, the chief executive of medical research charity LifeArc, in London. It will help to build confidence in more-tailored approaches to treatments for rare conditions that are often driven by unique genetic mutations, she adds. How does the vaccine work? The vaccine, called intismeran, doesn’t prevent a person from developing cancer in the first place, rather it seeks to prevent it from recurring. The study enrolled around 1,100 people with advanced melanoma that had been completely surgically removed. They received either the vaccine combined with an immunotherapy drug called pembrolizumab, which is used to treat the cancer, or they received pembrolizumab alone. The vaccine’s developers Merck, in Rahway, New Jersey, and Moderna, which is headquartered in Cambridge, Massachusetts, announced on Wednesday that people on the combined treatment survived for longer without recurrence than did those who received only pembrolizumab. The companies said that they plan to present more-detailed data at an upcoming medical conference. To create intismeran, a sample of a person’s tumour is sequenced to identify mutations that have developed in their cancer cells. These mutations mean that a cancer cell expresses abnormal proteins called neoantigens, which act like flags on its surface that the immune system attacks. An mRNA vaccine is developed according to each person’s cancer neoantigens, and once injected, it instructs the body to make the neoantigens — priming the body to recognize the threat. “We had never been able to train an individual patient’s immune system against their own tumour before,” says Adnan Khattak, a medical oncologist and an investigator in the trial at Hollywood Private Hospital in Nedlands, Australia. Until now, personalized cancer treatment often meant identifying specific abnormalities in a person’s cancer, such as the BRAF mutation, a gene alteration that occurs in about 50% of melanomas, and matching them to the right drug. In this study, an entirely new drug was created for each participant, says Cheetham. Although the latest trial results show that intismeran reduced the risk of recurrence, Khattak says that participants will need to be monitored for many years to determine whether the treatment extends their lifespan. What are the challenges of making these types of vaccine? The personalized nature of the vaccines is the biggest challenge for widespread use, says Cheetham. After collecting a sample of a person’s cancer, each vaccine can take several months to make. Some people with advanced cancers might not survive long enough, he adds. Khattak says that Moderna uses artificial-intelligence tools to identify which neoantigens are most likely to trigger a strong immune response. After the researchers narrow these down experimentally, a limited set are included in the vaccine design for the individual, he adds. Finding enough people to participate in the intismeran vaccine trial was also challenging, says Khattak. Misinformation about the safety of COVID-19 mRNA vaccines made it difficult for some centres in the United States to recruit participants, he adds. What other cancer vaccines are being tested? Several other groups are working on personalized cancer vaccines. Merck and Moderna are trialling the same personalized vaccine approach in a phase I trial for pancreatic, gastric and lung cancers. Biotechnology company BioNTech is also trialling personalized vaccines for colorectal, pancreatic and triple-negative breast cancers. Shenzhen Xinhe Biomedical in Shenzhen, China, is trialling a personalized vaccine for gastric and liver cancers.
发布时间:2026-08-20 Nature
The US National Science Foundation has been a major funder of basic science in the United States. Credit: Mark Schiefelbein/AP Photo/Alamy The US National Science Foundation (NSF) will award about 30% fewer new research grants this fiscal year than in the last one, Nature has learnt. The steep drop continues a pattern that began last year, after US President Donald Trump took office, leaving the NSF with the lowest number of new grants awarded in more than four decades. White House rolls out AI funding — and signals a new era for US science A major funder of basic science, the NSF struggled to make awards this year with a workforce that has been cut by the Trump administration and uncertainty around the funds available for spending. But the decline in new grants in 2026 can now be attributed mainly to US$1 billion of the agency’s $8.8-billion budget being held in a central account, inaccessible to core grant-issuing programmes. Staff members, who spoke to Nature on condition of anonymity out of fear of reprisal, say that much of that money is being allotted to a White House project called the Grand Research Challenges, which is aimed at scientific fields such as advanced materials and artificial intelligence. The agency had issued 5,684 new grants as of 19 August, according to Grant Witness, a non-profit effort to track changes in US research funding. And internal NSF data show that there are around 400 grants waiting at its Office of Award Management (OAM) for processing. Staff members were required to submit all new proposals to the OAM by 3 August, so the final number of new grants issued for this fiscal year, which ends on 30 September, will almost certainly be about 6,100 (see ‘Grants throttled’). That’s 46% fewer than the average for 2021–24, before Trump took office. The last time this number was so low was in the early 1980s. Source: Grant Witness/NSF data Many proposals that have been submitted by researchers and assessed by peer reviewers are in “pending purgatory”, says Jarett Wilcoxen, a chemist at the University of Wisconsin–Milwaukee. The proposals have not been declined, but they haven’t been fully approved and awarded money either. He submitted a grant proposal in late 2024 for an instrument that would be used by his laboratory and 20 others in the region. “It’s disappointing to see that the funds aren’t being allocated,” he says. “It’s a big impact on student training, and that student training is going to have a ripple effect from academia to industry.” A spokesperson for the NSF said in a statement that the agency “is actively investing in foundational research across the sciences and engineering” consistent with priorities laid out by the Trump administration. It is also “focusing on longer awards with larger funding amounts” to lessen researchers’ administrative burden, among other goals, they said. The spokesperson did not directly respond to questions about the withheld funds. The $1 billion in the central account can be spent next year, because the NSF has two years to spend funds assigned by the US Congress, which sets federal budgets. But withholding this much of the agency’s budget in one year is unprecedented, says Neal Lane, a physicist who directed the NSF from 1993 to 1998 under former president Bill Clinton. “I would never have imagined it happening under previous administrations.” Withheld funds Early in the 2026 fiscal year, the NSF was slowed down in its grant-making by a 43-day US government shutdown. This forced the agency to reschedule hundreds of meetings at which panels of independent scientists gather to review grant proposals. Then the NSF waited until mid-April to release funds so that its programme officers could begin making awards. Entire NSF science advisory board fired by Trump administration But staff members were dealt another blow in July, when the NSF clawed back some $300 million from two of its divisions (called directorates) without explanation, forcing programme officers to pull back more than 150 research proposals that had already been reviewed and recommended for funding. It has since become clear that the $300-million clawback was added to a larger pool of money that the NSF is holding centrally for the White House’s Grand Research Challenges project. An internal ledger seen by Nature describes the total amount of the pool as $1,016,862,632. It’s unclear who ordered the withholding of these funds. Another chunk of money in this pool — about $110 million — comes from the NSF’s education directorate. That amount had been allotted for this fiscal year to three diversity programmes that the US Department of Justice last week ruled unconstitutional because they discriminate by race or sex. The programmes aimed to diversify the scientific workforce by improving science education for under-represented minorities and providing them with financial support. All told, spending by nearly all of NSF’s eight main directorates is being curtailed by between 20% and 40% relative to the previous year. These reductions have come despite Congress’s directive that the agency not reduce spending for any of its directorates by more than 5% relative to fiscal year 2024. Withholding $1 billion — one-eighth of the NSF’s research budget — could land the agency in murky legal waters. “The larger the amount, then the more it looks like you’re not really trying to faithfully administer the programme” set by Congress, says Zachary Price, a specialist in constitutional law at the University of California College of the Law in San Francisco. A new approach Another reason why the NSF is funding fewer new grants this year has to do with changes in its approach to spending. Historically, the agency has issued ‘multi-year’ awards that disburse money through annual payments for a fixed number of years. Now, staff members say that they are prohibited from making multi-year awards in most cases. An analysis by Grant Witness bears this out and shows that the NSF is instead paying the full amount for awards up front, and paying the remaining amount for previously issued multi-year awards as a lump sum. This way, even if the agency spends the same overall amount, less goes to new awards. All of the NSF’s directorates are awarding fewer new grants, but the hardest hit is the social, behavioural and economic sciences (SBE) directorate, which the White House proposed eliminating in its 2027 budget request to Congress. SBE has so far awarded 84 new grants this year, about 11% of its average, mainly in areas of artificial intelligence, cognitive neuroscience and decision-making. Much of its portfolio, such as sociology, archaeology, political science, economics and geography, has received zero new awards. “I don’t think they’ve realized yet that there’s no awards,” one NSF staff member says of researchers in those fields. “That’s going to be clear soon.”
发布时间:2026-08-20 Nature
Paper introductions and discussions show more signs of AI use than results sections. Credit: Laurence Dutton/Getty The use of artificial intelligence to write scientific papers could be much more prevalent than was previously thought. That’s the upshot of a study that estimates that almost nine out of ten papers published in December 2025 in a major biomedical-article database showed signs of AI-assisted writing. The study, which was posted on the arXiv preprint site on 12 August1 and has not yet been peer reviewed, puts the rate of usage of AI large language models (LLMs) at 77% for papers archived in the PubMed Central repository and published in the whole of 2025, and 52% for those published in 2024, suggesting LLM use is on the rise. (The study included only papers written in English). These figures are substantially higher than previous estimates of LLM use in the scientific literature. A 2025 paper authored by some of the same researchers that analysed abstracts of papers in PubMed, rather than the full text, puts the figure at at least 13.5% for 20242. Meanwhile, a 2026 study that looked at papers across academic disciplines estimated that 57% of 2025 papers were probably AI-influenced3. Dmitry Kobak, a computer scientist at Ghent University in Belgium and co-author of the preprint and the 2025 paper, says he was initially sceptical of the calculations in the latest study: “I was sure that we did something wrong.” But further checks convinced him that the data stood up. Like many previous studies, the latest work analysed the frequency of words commonly used by LLMs to detect signs of their deployment in papers. Kobak attributes the higher figure to the particular method his team used this time around, which is more sensitive to LLM use and therefore more likely to give a higher figure. This method, which yields direct estimates for AI use rather than lower bounds, increased the LLM use rate for 2024 abstracts from 13.5% to 31%. The authors also say that the figures are consistent with the findings of a survey conducted in 2025 — in which 71% of researchers said they use AI for writing assistance — and that the true figure is probably higher than people admit or report in surveys. Other researchers told Nature that the high rates of estimated LLM use reported in the latest paper could make sense given the widespread use of LLMs. They also cautioned that the figures in the study might not be representative of the entire scientific literature and that more analysis is needed to fully understand the rates of usage more broadly. But the results indicate that LLMs are here to stay, says Kyle Siler, a social scientist at the University of Toronto, Canada, and author of the 2026 study that estimated lower LLM use3. “The toothpaste is out of the tube, and it’s not going back.” Abstracts versus methods The latest study also found that LLM use was more frequent in abstracts, introductions and discussion sections than in methods and results sections. An estimated 78% of discussion sections in December 2025 papers showed signs of AI, compared with 58% of results sections. AI-assisted results sections could be worrying, says Kobak, because of the propensity of LLMs to fabricate, or ‘hallucinate’, data. Using LLMs to write or edit introductions, meanwhile, could skew the leading ideas in a field. “Whatever bias the LLM may have will just suddenly permeate the literature,” says Kobak. One problem with current AI-detection methods is that they can’t distinguish between a text generated by AI and one that was simply edited for grammar, says Andrew Gray, a bibliometrics support officer at University College London and author of a 2025 study that estimated lower LLM use in 2024 than do the latest preprint’s findings4. This makes it more difficult for journals to filter submissions for low-quality AI content, he says, because all AI-assisted papers will have similar features regardless of how much writing the LLM did. The latest study also found that LLM use was more common when papers were written by authors based in countries where English was not the predominant language. This is not surprising, says Kobak, given that LLMs are commonly used by people who do not have English as their first language to translate text and polish grammar. Siler says that future research should focus on determining not just who is using LLMs, but how they are using them. To help to differentiate between legitimate AI use and AI slop, many journals now ask researchers to acknowledge how and when they use AI in their submissions. But researchers must still use caution when using these tools, says the latest study’s first author Lena Holzwarth, a cognitive scientist who was involved in the work while at the Eberhard Karls University of Tübingen in Germany. Wrestling with thoughts and putting them into words is an essential part of the scientific process, she says, and relying on LLMs to write papers eliminates this important struggle.
发布时间:2026-08-20 Nature
Two-year-old Giselle Ghattas is fearless, funny and affectionate, according to her parents. She loves diving headfirst down playground slides and climbing onto anything she can reach. Giselle seems like any other lively toddler, despite having a rare genetic disorder that threatens to rev her immune system at full throttle. The controversial embryo tests that promise a better baby The condition, known as familial haemophagocytic lymphohistiocytosis (HLH), causes fever and inflammation and can spiral into organ failure, neurological damage and death in as little as months if it goes untreated. And that’s the case for many children with the disease. Because HLH is rare and variable, clinicians often misdiagnose it or fail to catch it early. But Giselle is not like most people with HLH. Her parents, Justin Ghattas and Scarlett Morwood, enrolled her in BabyScreen+, a study in Australia, which uses whole-genome sequencing to screen newborns for genetic variants associated with severe, treatable diseases. Ghattas and Morwood came across the study on social media. “If I had just kept scrolling on Facebook and not joined, then we’d probably still be, potentially even now, working out: ‘What’s wrong with her?’” says Ghattas. Instead, Giselle received a bone-marrow transplant at six months old, and despite some complications, she has recovered and begun to thrive. According to her physicians, she will probably not need any more treatment beyond routine monitoring, says Ghattas. BabyScreen+ is just one of dozens of initiatives around the globe that is assessing the feasibility of expanded genomic newborn screening. Early results have shown that these approaches can flag treatable conditions that aren’t covered by conventional newborn screening, which checks for up to a few dozen conditions. If the trials prove successful more broadly, genome sequencing could revolutionize current practices for newborn screening, providing in-depth information about a range of deadly and debilitating conditions, including some cancers. For Wendy Chung, a physician-scientist at Boston Children’s Hospital in Massachusetts, the promise of genomic newborn screening was evident long before she became a principal investigator on GUARDIAN, one of the largest genomic newborn-screening studies so far. “Newborn screening is, I would argue, one of the most, if not the most, successful public-health initiatives in the sense that it leaves no one behind,” she says. “GUARDIAN is really adding another modality to enhance what already is a very successful public-health initiative.” But, for some, optimism is tempered by practical questions about the process, which is currently costly and difficult to scale up for broader implementation. Some also have ethical questions about applying genome sequencing to thousands of people, says Robert Green, a medical geneticist at Harvard Medical School in Boston. “There’s a lot of controversy around this,” he says, including privacy issues and the potential for discrimination by insurance companies. And not everyone has had the positive experience with genomic newborn screening that Giselle Ghattas’s family has. Early results Current newborn-screening practices in many parts of the world use a dried blood spot taken from the heel shortly after birth. Laboratory tests screen the blood for a number of congenital disorders, mostly through chemical analysis of proteins and metabolites rather than through gene sequencing. US guidelines recommend testing for 66 conditions, which are mainly metabolic disorders. Many countries screen for fewer. France tests for 16 conditions, for example, and the United Kingdom screens for 10. Of the nearly 3.6 million infants born in the United States each year, 98% undergo this kind of screening, and it has been predicted that roughly 6,600 — about 1 in 600 — will test positive for a condition1. Genomic newborn screening would drastically expand what can be detected. Using DNA from the same dried blood spots collected for conventional screening, pilot studies are sequencing hundreds of genes or even the entire genome, with some screening for more than 700 disorders. If implemented broadly, this approach could identify thousands — perhaps millions — of children worldwide with rare genetic diseases. Green co-led the BabySeq Project. Initiated in 2013, it was one of the first studies to evaluate genomic sequencing in healthy newborns. Across two independent BabySeq trials, around 1,045 infants were enrolled, including 432 who were chosen at random to undergo genomic sequencing. Among the infants whose genes were sequenced, approximately 11% had disease-associated genetic variants, and roughly one-third were already showing early signs of disease2,3. These ‘master’ proteins protect us from deadly mutations — and could inspire new drugs More than a decade later, the BabySeq Project has been joined by a growing number of larger genomic newborn-screening studies. These programmes provide results — not diagnoses. Potential issues require confirmatory testing, with some findings ultimately being confirmed and others ruled out. As genomic newborn screening expands, scientists are beginning to see how this process unfolds on a larger scale. At a conference last October, researchers shared preliminary results4 from the GUARDIAN study from 15,000 newborn participants out of a planned 100,000. Whole-genome sequencing identified 411 infants (2.7%) whose screening results were subsequently confirmed through diagnostic testing. The vast majority were not identified through current newborn screening because the conditions they have are not included in those tests. In some cases, the findings prompted life-saving interventions, including bone-marrow transplants5. Several studies published early findings in 2025 with comparable results. The BabyScreen+ study6, in which Giselle Ghattas was enrolled, screened 1,000 newborns and reported confirmed findings in 1.6% of participants. In Belgium, the BabyDetect study7 confirmed genetic conditions in 1.8% of nearly 4,000 infants, including 0.8% whose conditions would have been missed by conventional newborn screening. For researchers leading these initiatives, the findings provide important evidence that the technology is effective and that the approach is acceptable to families and consistent. “Even though we’re based in different health-care systems, and we’ve taken some slightly different approaches to some of the components, many of the results are actually quite similar, which is reassuring,” says Zornitza Stark, a clinical geneticist at the Murdoch Children’s Research Institute in Parkville, Australia, and co-leader of the BabyScreen+ study. Gene-list considerations In their effort to maximize the benefits of genomic screening, researchers must first decide which genes should be on the panel — a question that has proved surprisingly contentious. Existing studies vary considerably. BabyScreen+ analyses 605 genes, whereas the BabyDetect study screens 405. The GUARDIAN study began with about 250 genes before expanding to 450, whereas North Carolina’s Early Check programme evaluates 169. Most programmes focus on severe childhood-onset disorders that have some form of intervention. As the number of studies has grown, however, researchers have begun to uncover the limits of current knowledge about the relationship between genetic variants and disease. In the GUARDIAN study, for example, infants with variants in the epilepsy-associated gene SCN1A differed notably from one another in the age of onset for seizures. Even variants in well-characterized genes don’t always reliably predict disease, and disease databases do not always agree on how harmful a given variant is. “Understanding genotype–phenotype correlations and fine-tuning reporting requires very large numbers of individuals to be tested,” says Stark. “We’re not going to get there unless we actually test thousands, if not millions, of individuals.” One of the central aims of genomic newborn-screening studies is determining which genetic changes cause disease and which prove benign. In the GUARDIAN study, 64 of 475 infants who were flagged initially as potentially having a genetic disorder showed no signs of disease at the time of confirmatory testing. The Early Check study reported 22 such cases among 50 flagged infants, whereas the BabyScreen+ study reported none. The approach to predictive medicine that is taking genomics research by storm The second challenge is deciding which conditions are sufficiently actionable to justify screening. “You only do screening if detecting it before it becomes clinically diagnosed leads to better outcomes,” says Ned Calonge, a physician at the Colorado School of Public Health in Aurora and the outgoing chair of a disbanded advisory group that made newborn-screening recommendations in the United States. But what constitutes a meaningful health benefit remains open to debate. Accordingly, some genomic newborn-screening studies have taken an exploratory approach to designing their gene lists. Some studies enable parents to opt in for tests for which the clinical utility is less well established than it is for the standard panel. In the GUARDIAN study, for example, all participating parents who consented to their child undergoing screening for a primary list of treatable conditions were given the option to add a second panel of neurodevelopmental disorders associated with seizures. Although many of these conditions have no cure, investigators say that identifying infants who are affected might enable earlier treatment of seizures, which could improve outcomes. Parental buy-in For parents, the effects of such broad screening panels can vary drastically. For Dorka Nemes, the results were transformative. Her daughter, Safi Ford, participated in the UK’s Generation Study and screened positive for isolated growth-hormone deficiency, a condition that limits growth. Nemes has the same condition, as do her brother and father. Safi started growth-hormone therapy at just 6 months of age, whereas her mother was not treated until the age of 17, after much of the critical period for maximizing growth had already passed. Stories like Safi’s are one reason that many patient advocates see the potential of broader genomic screening. Jennifer Handt, whose son has Duchenne muscular dystrophy and who helped to advocate for its inclusion in current newborn-screening panels in the United States, emphasizes that early symptoms rarely go unnoticed by families. “You’re not living in some blissful existence where you think your child is fine,” she says. Watching a child struggle and then facing a delayed diagnosis can feel like a “double injury”, she says, one that expanded newborn screening could help to prevent. Safi Ford, daughter of Dorka Nemes and Cameron Ford, was able to start treatment for a genetic condition earlier than most children.Credit: Mel Yeneralski/Cambridge University Hospitals NHS Foundation Trust But not every family leaves satisfied. Drew Villano gave birth to a healthy baby boy, Harmony, in April. According to Villano, a programme coordinator approached her about enrolling in the GUARDIAN study shortly after delivery. She signed up. Five weeks later, the phone rang. A genetic counsellor told her that her son carried a variant in a gene associated with the rare genetic disorder Smith–Magenis syndrome. Villano says the genetic counsellor struggled to explain the significance of the finding over several phone calls and ultimately told her she could look up the condition online. Villano, a writer and owner of a real-estate company, said that the information she received wasn’t very reassuring. Ultimately, more testing showed that the variant was unlikely to be disease-causing, but the lack of clear, digestible explanations throughout the process, she says, left her shaken. “When the margin of error involves human lives and not just data, there’s a certain level of care that you should be taking,” she says. Chung, who leads the GUARDIAN study, says the programme’s coordinators and genetic counsellors are well trained and should advise families not to go down an “online rabbit hole” when questions arise. Although she says she does not wish to minimize the stress that Villano describes, she adds that the response falls at the far end of a spectrum of experiences with the study. More broadly, Alban Ziegler, a clinical geneticist at Toulouse University Hospital in France, who previously worked on the GUARDIAN study, says that parents are resilient in the face of findings that are troubling but uncertain. “We see that parents are able to cope with the news,” he says. Rolling out screening Roughly 130 million babies are born worldwide each year, yet most genomic newborn-screening studies still take years to recruit only a few thousand participants, sequence their genes and interpret and return results. “We have not made any inroads in terms of being able to answer, ‘How do we get from this small pilot demonstration to that sort of scale?’,” says Stark. For conventional screening, many US states have yet to implement fully every condition recommended by federal guidelines, partly owing to stretched lab capacity. Incorporating large-scale genomic sequencing alongside existing screening programmes requires substantial investments in lab infrastructure, data analysis and workforce. CRISPR’s next act: the companies editing the epigenome to treat disease And costs would be higher than they are for conventional screening. At the launch of the GUARDIAN study, Chung estimates that sequencing and analysis cost just under US$1,000 per child. By comparison, Minnesota — one of the highest-spending states for newborn screening — earmarks roughly $250 per infant. As sequencing capacity expands and data interpretation becomes increasingly automated, Chung expects the cost of genomic newborn screening to eventually fall by at least half. Even so, whether state public-health programmes would be willing — or able — to absorb the costs remains uncertain. Florida might hold the answer to that question. In 2025, lawmakers passed the Sunshine Genetics Act, creating a five-year pilot programme that aims to enrol 100,000 newborns and screen for more than 750 genetic conditions. “Hopefully, we can be the model for other states,” says Pankaj Agrawal, a physician-scientist at Holtz Children’s Hospital in Miami, and co-leader of the programme. The United Kingdom has taken a similarly ambitious approach. Backed by £650 million (around $880 million) in UK government funding for genomics, the Generation Study is now more than halfway towards its goal of recruiting 100,000 newborns. “I think the government, at the moment, is very supportive of the use of genomics in health care,” says Meekai To, a maternal- and child-health clinician who is involved in the study, which is run by the London-based company Genomics England. On a national level, the United States is also beginning to shift from small research studies towards implementation. In 2025, the National Institutes of Health awarded funding for BRIDGES-NBS, a project co-led by Green that plans to sequence the genes of 30,000 newborns over three years, across six states and Puerto Rico. The initiative engages public-health labs to determine whether genome sequencing can be integrated into existing newborn-screening programmes. Even if these studies prove successful, researchers expect implementation to happen gradually. Chung says that broad genomic sequencing should not replace the dried-blood-spot tests. Instead, she expects individual genes or groups of similar genes to be incorporated incrementally in current newborn screening. Green says that newborn screening might ultimately become only the first chapter in a much broader vision. Rather than viewing a genome sequence as a one-time test, he imagines it as a lifelong clinical resource that could be reanalysed as individuals develop symptoms later in life. In that future, the value of genomic sequencing would extend well beyond the newborn period. That vision remains years away, but many researchers think that the field is now taking its first meaningful steps towards it. “We had really this feeling when launching the study that it was a potential breakthrough. It’s not so frequent, at least in my career, having this feeling,” says Ziegler. “I hope my grandchildren will benefit from it.”
发布时间:2026-08-19 Nature
The South African parliament has yet to debate the proposed natural-sciences bill. Credit: Franz Aberham/Getty Natural scientists in South Africa could be imprisoned for up to a year for failing to register with a government-backed regulatory body, according to proposed legislation that is to go before South Africa’s parliament. Under the terms of the proposed law, it will be mandatory for some scientists to register with an existing body called the South African Council for Natural Scientific Professions (SACNASP). SACNSP was set up in 2003 and all natural scientists in the country were meant to have registered with it, but many never did. “Our goal is not to be gatekeepers, but to professionalize the natural sciences through registration and regulation,” SACNASP’s acting chief executive Matshidiso Matabane told Nature. “It is our obligation to not only protect the profession itself, but the public and the environment,” she added. The proposed legislation states that it aims to “protect and promote the public interests by regulating the conduct of practising natural scientists” and “to ensure the protection of the environment”. It would regard natural scientists similar to engineers and healthcare professionals, who need to register with their respective regulatory bodies: the Engineering Council of South Africa and the Healthcare Professions Council of South Africa. However, leading scientists have told Nature that many researchers are unaware of the law, or of the possible penalty of a jail term. A date for the legislation to be debated in parliament has yet to be set. “It’s a money-making scheme,” says Nithaya Chetty, a physicist and dean of science at the University of the Witwatersrand, Johannesburg, who is not registered with SACNASP and was unaware of the proposed law until Nature brought it to his attention. He says he is concerned that the draft bill “gives the SACNASP board considerable future power”, and adds that it is ambiguous in its definitions. Lise Korsten, a plant scientist at the University of Pretoria and former president of the African Academy of Sciences, says that she, too, was unaware of the provision for jail time in the proposed law. However, Korsten, who is also not registered with SACNASP, says she supports accountability for scientists who are involved in consulting. Fraudulent ‘experts’ are “a big problem” for the country. “It’s for public protection,” says Korsten. New law for old The text of the draft bill, which is dated 16 March, repeals the previous 2003 legislation on SACNASP. It clarifies the purpose and governance of the council, and introduces the possible penalty of a criminal record: “practising natural scientists” who do not comply with the legislation could be sentenced to up to a year in jail. Public comment on the bill closed in May, and it will now be presented in the country’s parliament for debate, although the timeline for this is unclear. The text defines “practising” in the natural-sciences context as “rendering of a service or provision of advice in the natural scientific profession”, whether for remuneration or for free. Those who teach at a recognized educational institution, and those who develop policy on natural science for the government, are not required to register. But it is not clear in the text if academics who teach or do research need to register if they consult with or advise other organizations. SACNASP referred all questions regarding the bill to the South African government's Department of Science, Technology and Innovation. The department had not responded to Nature's questions at the time of publication. The bill also does not include precise details about the process that would be used to prosecute scientists who fail to register. But it does say that a code of conduct will be drawn up in consultation with scientists’ representative organizations (which are also required to register). High costs A full professional SACNASP membership costs 1,920 South African rand (US$119) annually, but there is also a one-off registration charge, which is 2,560 rand for South Africans and 5,410 rand for foreign scientists. The minimum wage in South Africa is 30.23 rand an hour — about 5,200–5,900 rand a month. At present, about 21,000 scientists are registered with SACNASP, Matabane says. These members span 26 disciplines, including mathematics, geological sciences and the physical sciences. No data are available on how many of the country’s academics have not registered. Under South Africa’s current code of conduct for scientists, published in 2022, scientists must, among other requirements, disclose to their employer or client any conflicts of interest; refrain from damaging another person’s reputation without cause; and “uphold the dignity, standing and reputation of the natural scientific professions”. Legal guidance, updated earlier this year, makes it mandatory for any registered member to report unprofessional or improper conduct among their colleagues and asks them to be “vigilant” for behaviour that brings their discipline into “disrepute”. According to the updated bill, if an individual is found guilty at a disciplinary hearing of the SACNASP board, they can be fined or even have their membership revoked, meaning that they can no longer practise as a natural scientist. In a parliamentary briefing in May this year, SACNASP’S legal manager Tsapo Seima said that SACNASP had received about 20 complaints against registered scientists, either from members or through an anonymous channel. Matabane says that there were cases of scientists undertaking work for which they were not qualified, for example. SACNASP does not investigate scientific integrity, predatory publishing or plagiarism, which are overseen by university structures, Matabane adds. Risks to institutional autonomy Chetty concedes that there could be a case for urging scientists who consult for industry to join SACNASP. “But being an academic is something that is unique. You teach, you research under the principles of institutional autonomy,” he says. “They will continue to try to register scientists, and we are going to continue to balk at the idea.” Himla Soodyall, a geneticist and executive officer at the Academy of Science of South Africa, was also unaware of the proposed jail time for failing to register. She says she is comfortable with the idea of registering scientists, but questions how it will benefit them. SACNASP claims to provide mentoring and professional development, “but it comes at a high cost”, she says. “What would the benefit be at the end of the day to the individual?” But Matabane says it is about ensuring that people are protected from harm from scientists who do not have the expertise they claim to. “Professional registration provides assurance that the individual has met the recognized standards of education and competence” and is “committed to practising in accordance with our code of conduct”.
发布时间:2026-08-19 Nature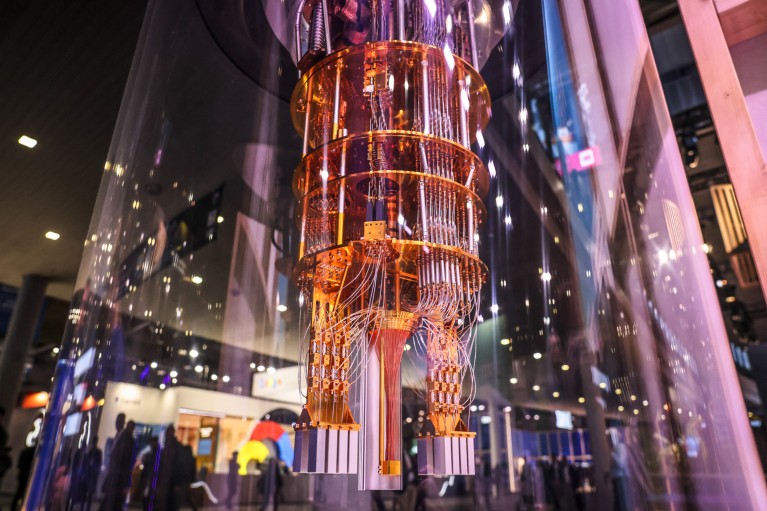
Quantum computers, such as this one shown at this year’s Mobile World Congress in Barcelona, Spain, could run programs that have been almost completely generated by artificial-intelligence tools. Credit: Angel Garcia/Bloomberg/Getty ‘Vibe coding’ is moving into quantum computing — a field in which programming has notoriously required sophisticated skills. To lower this barrier, researchers at Pasqal, a quantum-computing start-up company in Paris, have developed an artificial-intelligence tool that can turn an English-language prompt into quantum computing code and then autonomously run it on a quantum computer. The agent, which is described in a preprint posted on the arXiv server last month1, often requires feedback from people with specialized knowledge to work properly. But its creators say that it still accelerates the work and it could make quantum computers — machines that can greatly speed up certain calculations by harnessing quantum phenomena — accessible to a wide range of researchers. Christophe Jurczak, a co-author of the work and one of Pasqal’s co-founders, says the agent enabled him to run experiments that would commonly require a team of physicists who are highly specialized in quantum-computing. “And I can do it on my own, from my couch in Dallas, Texas.” Quantum vibes In classical, as opposed to quantum, computer programming, vibe coding refers to an extreme version of AI-aided software engineering, in which the user describes to an AI tool what they want a piece of software to do, and the machine — perhaps after a few adjustments according to the user’s feedback — produces and runs a fully working program. Quantum simulations verified by experiments for the first time Frontier large language models (LLMs), such as Anthropic’s Claude, have displayed a grasp of quantum computing, and many researchers now use them to help write not just classical but also quantum code. To see whether such LLMs could go as far as quantum vibe coding, Jurczak and his collaborators familiarized frontier LLMs with the technical specifications of Pasqal’s quantum computers. They aimed specifically at streamlining the development of one of the most promising applications of quantum computers — quantum simulations. These involve tuning a quantum computer to resemble the behaviour of another physical system, such as a catalyst or a material with unusual magnetic properties. The quantum machine running the simulation could then predict the materials’ properties with calculations that would overwhelm a classical computer. In their study, the Pasqal team subjected the AI agent to three tests. In each case, they chose a physics paper describing a physical phenomenon that could, in principle, be simulated on a quantum computer, and asked the agent to write and execute the code to confirm this. Two of the test cases involved simulating materials in which atoms flip up or down, like tiny bar magnets, depending on the orientation of their neighbours. To model this phenomenon, the agent has to first translate it into a possible behaviour of a Pasqal machine — a quantum computer that encodes information in an array of atoms trapped with laser light. This crucial ‘translation’ step has typically required a team with expertise both in the physics of the materials being simulated and in quantum computing, says physicist Loïc Henriet, chief technology officer at Pasqal and a co-author of the study. But before running the quantum code on actual Pasqal quantum computers, the agent first tests it using ‘virtual’ versions that run on a classical computer. If the quantum code passes that test, it is then automatically sent to one of Pasqal’s quantum computers in Dhahran, Saudi Arabia, or to another in Sherbrooke, Canada. In all three tests, the agent demonstrated “a firm grasp of the hardware constraints”, the authors write. In one case, the authors tried to trick the agent by asking it to do a simulation that they knew would be too complicated to realize on the Pasqal machines available on the cloud, and the agent correctly explained why it couldn’t be done. In another, the agent required a lot of hand-holding from the human researcher to reach a “physically accurate implementation”, the authors say. Not your classical assistant “Their approach looks very interesting,” says Federica Surace, a quantum-computing researcher at Trinity College Dublin. Being able to automate the translation from conceptual work to quantum hardware “could change the way research is done in this field”, she adds. Other groups have created systems that have some of the capabilities of Pasqal’s agent. Nouhaila Innan, an applied physicist at New York University in Abu Dhabi has co-developed a customized version of the open-source LLM LLaMa to give it the ability to produce quantum code — although not yet to run it autonomously2. Still, she says, it can help her and her collaborators to solve problems in one day that would have taken four days before. Masaki Shiraishi, a physicist at Waseda University in Tokyo, says that Pasqal’s system could be powerful as an assistant for designing and performing quantum-computing experiments, even though it is not yet “a fully autonomous scientist”. Shiraishi and his collaborators have created software that automates several aspects of quantum computing3 without requiring access to external LLMs. He says that they are also developing a system similar to Pasqal’s but aimed at quantum algorithms. Mario Krenn, a physicist at the University of Tübingen in Germany, says Pasqal’s system highlights how the frontier LLMs, when cleverly harnessed, can now greatly speed up quantum-computing research. “It would have been an enormous effort if you had tried to do this just three years ago,” he says.
发布时间:2026-08-19 Nature